


Artificial Intelligence in Sentiment Analysis of Multilingual Wikipedia: Classifiers vs. Large Language Models
In the case of Wikipedia, sentiment analysis is a particularly interesting task. Encyclopedic articles are expected to follow the neutral point of view (NPOV) principle, which means that signals of positive or negative sentiment are often much more subtle than, for example, in product reviews or social media posts.
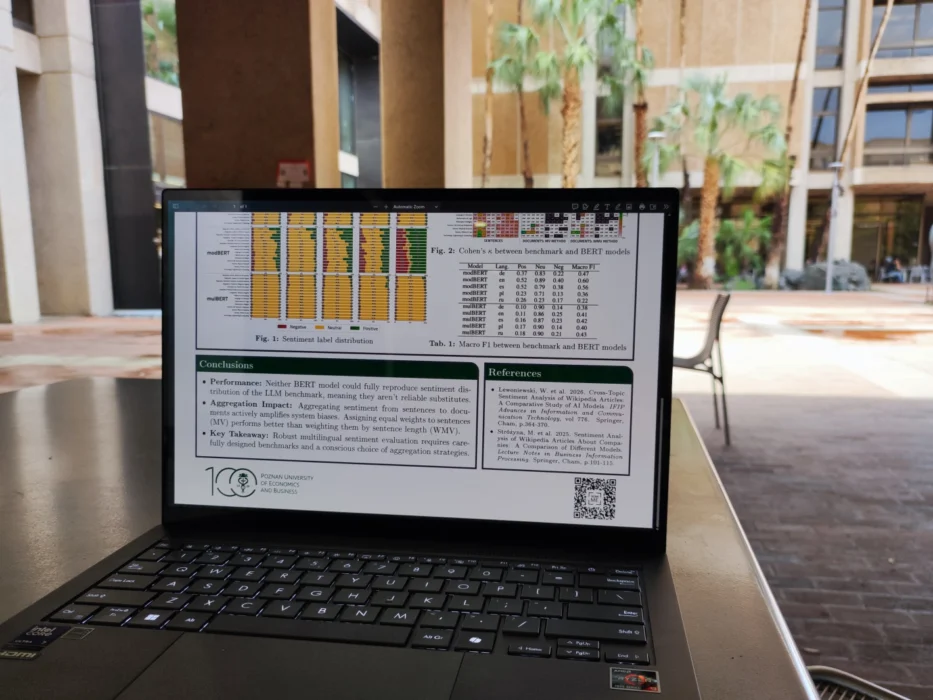
Our researchers analyzed Wikipedia texts in five language versions: English, German, Spanish, Polish, and Russian. Three large language models were used for annotation: GPT-5.2, Gemini 3.1 Pro, and Claude Opus 4.6. Each model evaluated every sentence three times, making it possible to examine both differences between the models and the consistency of each model’s responses across repeated runs. The results were then compared with those produced by two multilingual sentiment classifiers based on the BERT architecture.
Based on the model assessments, the researchers created a multilingual benchmark for sentiment analysis of Wikipedia texts. The reference dataset included only those sentences for which all three large language models produced the same classification across all nine evaluation runs. This highly restrictive criterion was intended to increase the reliability of the labels subsequently used to evaluate other models.
Another important outcome of the study is the public release of the research data on Kaggle. The dataset includes the data used to construct the benchmark as well as sentiment analysis results for five language versions of Wikipedia. Among other resources, it provides labels derived from the benchmark and from the evaluated models, as well as results obtained using two methods of aggregating sentence-level assessments to the article level. This makes the dataset suitable for reuse in tasks such as comparing new sentiment analysis models, investigating cross-linguistic differences, and conducting further experiments on assessing neutrality in encyclopedic texts.
The findings show that sentiment assessments can vary substantially depending on both the model and the language used. The authors also point out that sentiment in encyclopedic texts is often ambiguous and highly context-dependent, making its automatic detection a challenging research problem in multilingual natural language processing.
The paper was co-authored by researchers from the Department of Information Systems: Dr. Milena Stróżyna, Dr. Włodzimierz Lewoniewski, Izabela Czumałowska. The full paper is available through ACL Anthology. DOI: 10.18653/v1/2026.gem-main.63